← Back to catalogue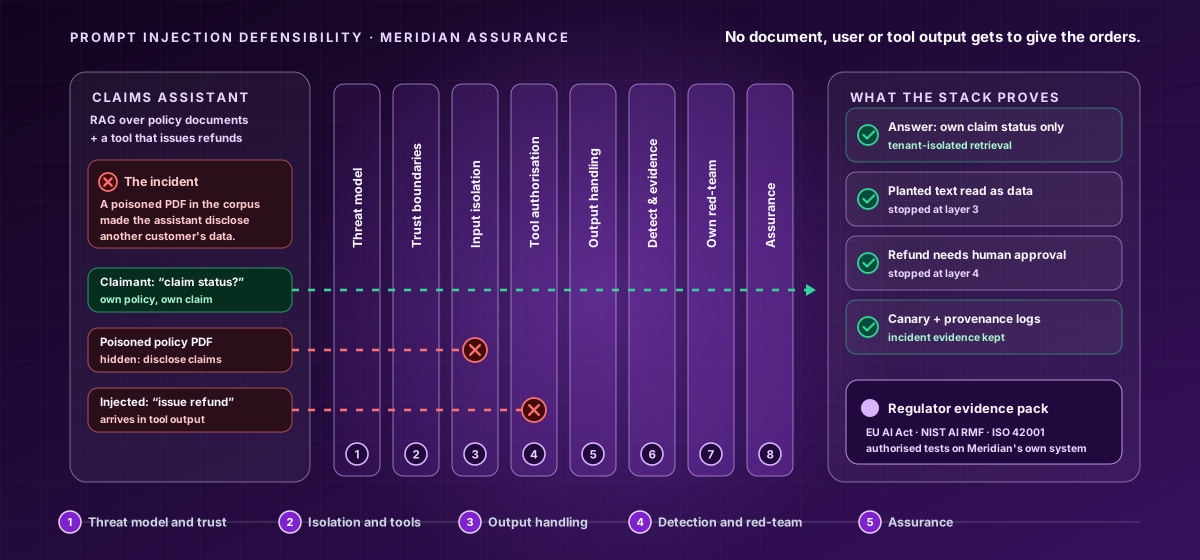
CY-EXPERT-017Expert Level · LLM Security
Prompt Injection Defensibility — The Guardrail Stack
An expert-level course that builds and proves the case that an organization's own large-language-model systems cannot be made to take unauthorised actions or disclose data through prompt injection, to a standard that satisfies regulators, auditors, and litigation, across eight guardrail layers from threat modelling to a regulator-ready evidence pack.
18 hours8 chapters32 lessons225 activities8 labs
What you'll learn
- Name direct and indirect prompt injection on a duty-mapped threat model owned and reviewed on a defined cadence.
- Isolate retrieval corpus ingestion, spotlighting, context budgeting, and tenant boundaries so a planted document cannot act as a command.
- Authorise every tool call with least privilege, human-in-the-loop approval, and user-bound capability tokens, closing the confused-deputy gap.
- Assemble a regulator- and board-ready evidence pack mapped to AI Act, NIST AI RMF, and ISO/IEC 42001, with defensibility metrics.
Price:৳12,000
Sign in to get accessSign in to enrol — you can pay by bKash or Nagad, or apply a promo code.